Video Diffusion Transformers (VDiTs) have demonstrated significant capabilities in high-fidelity video generation.
However, their ability to produce long-duration videos is fundamentally constrained by the quadratic complexity of
the self-attention mechanism. Recent clustering-based sparse attention methods improve the quality-speed trade-off by
grouping semantically similar tokens, but their practical efficiency remains limited by two bottlenecks: substantial
clustering overhead and low CTA utilization caused by irregular cluster-induced blocks. We propose HyperVAttention
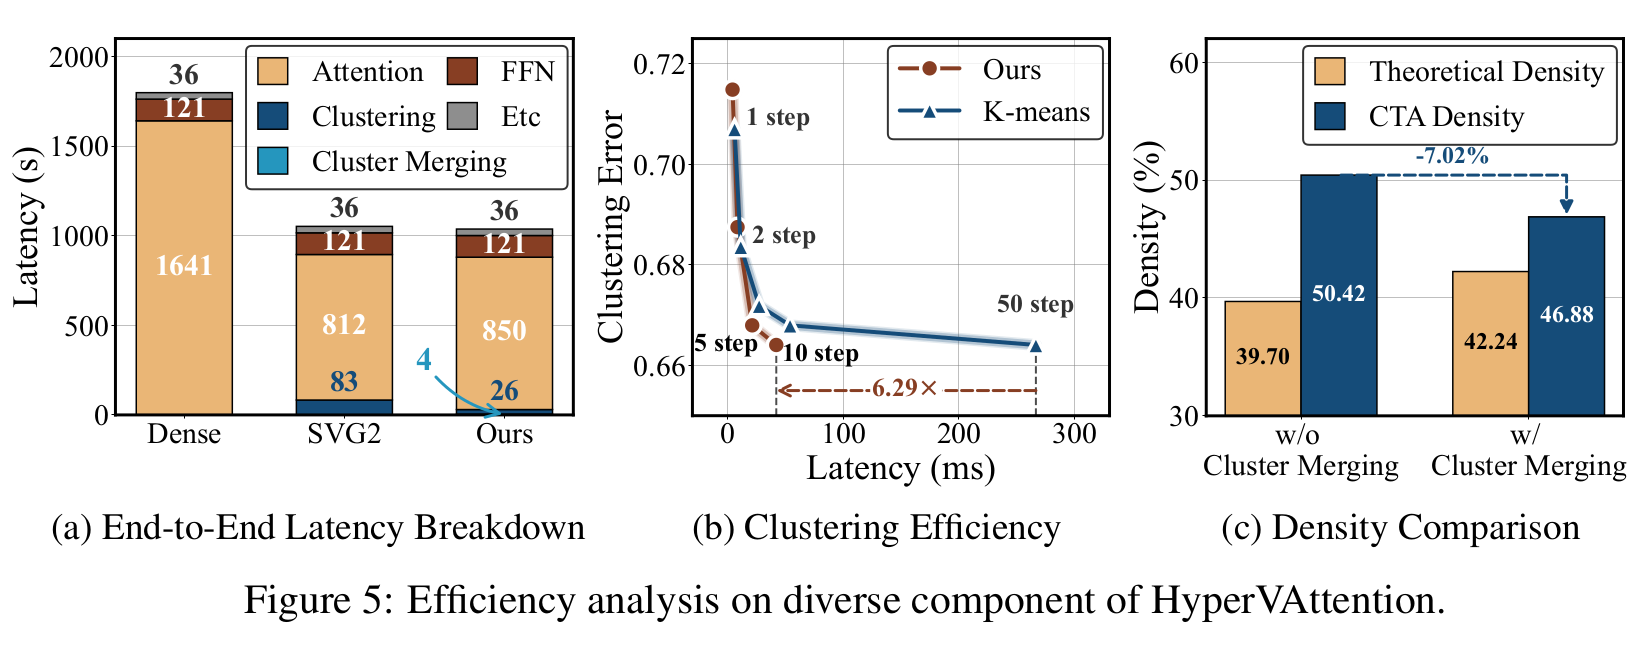
(HVA), a training-free sparse attention framework that addresses both bottlenecks jointly. To reduce clustering
overhead, we introduce 3D local-window clustering, which exploits the spatio-temporal locality of video tokens to
restrict centroid search to fixed local neighborhoods, and implement it with a custom Triton kernel for efficient
execution. We further propose a hybrid clustering strategy that performs full clustering only at anchor steps and
updates only subset tokens at intermediate steps, leveraging the temporal stability of cluster assignments across
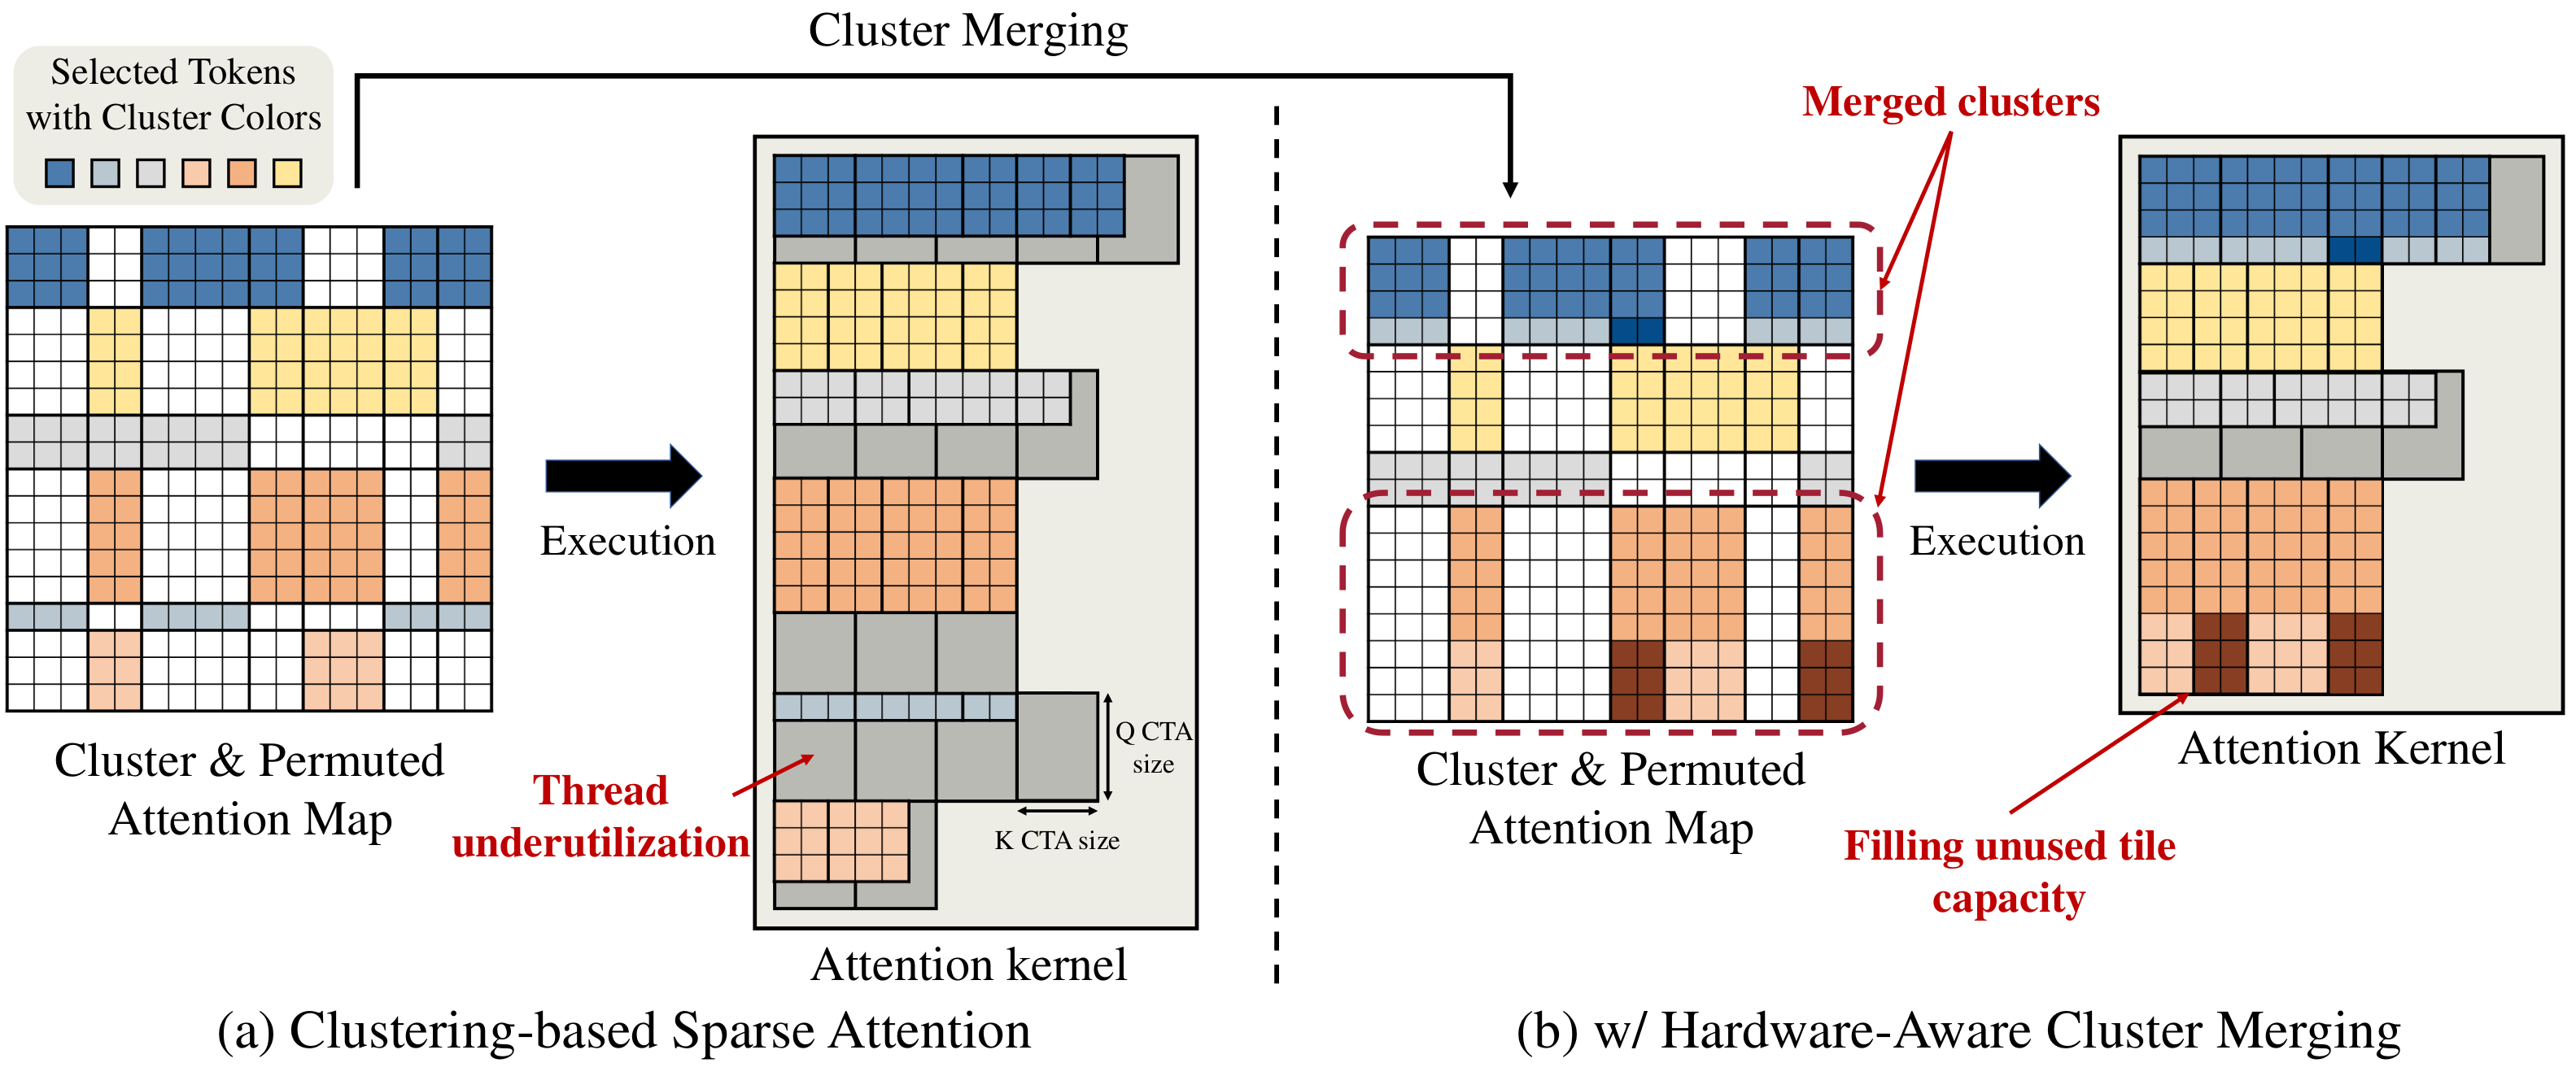
denoising steps. To improve CTA utilization, we present hardware-aware cluster merging that minimizes CTA-aligned
execution cost through parallel agglomerative merging, improving block density and approximation fidelity by utilizing
idle tile capacity. Together, these components reduce clustering overhead, avoid redundant updates, and better align
sparse attention with the fixed tile structure of modern GPU kernels. Experiments on Text-to-Video generation show that
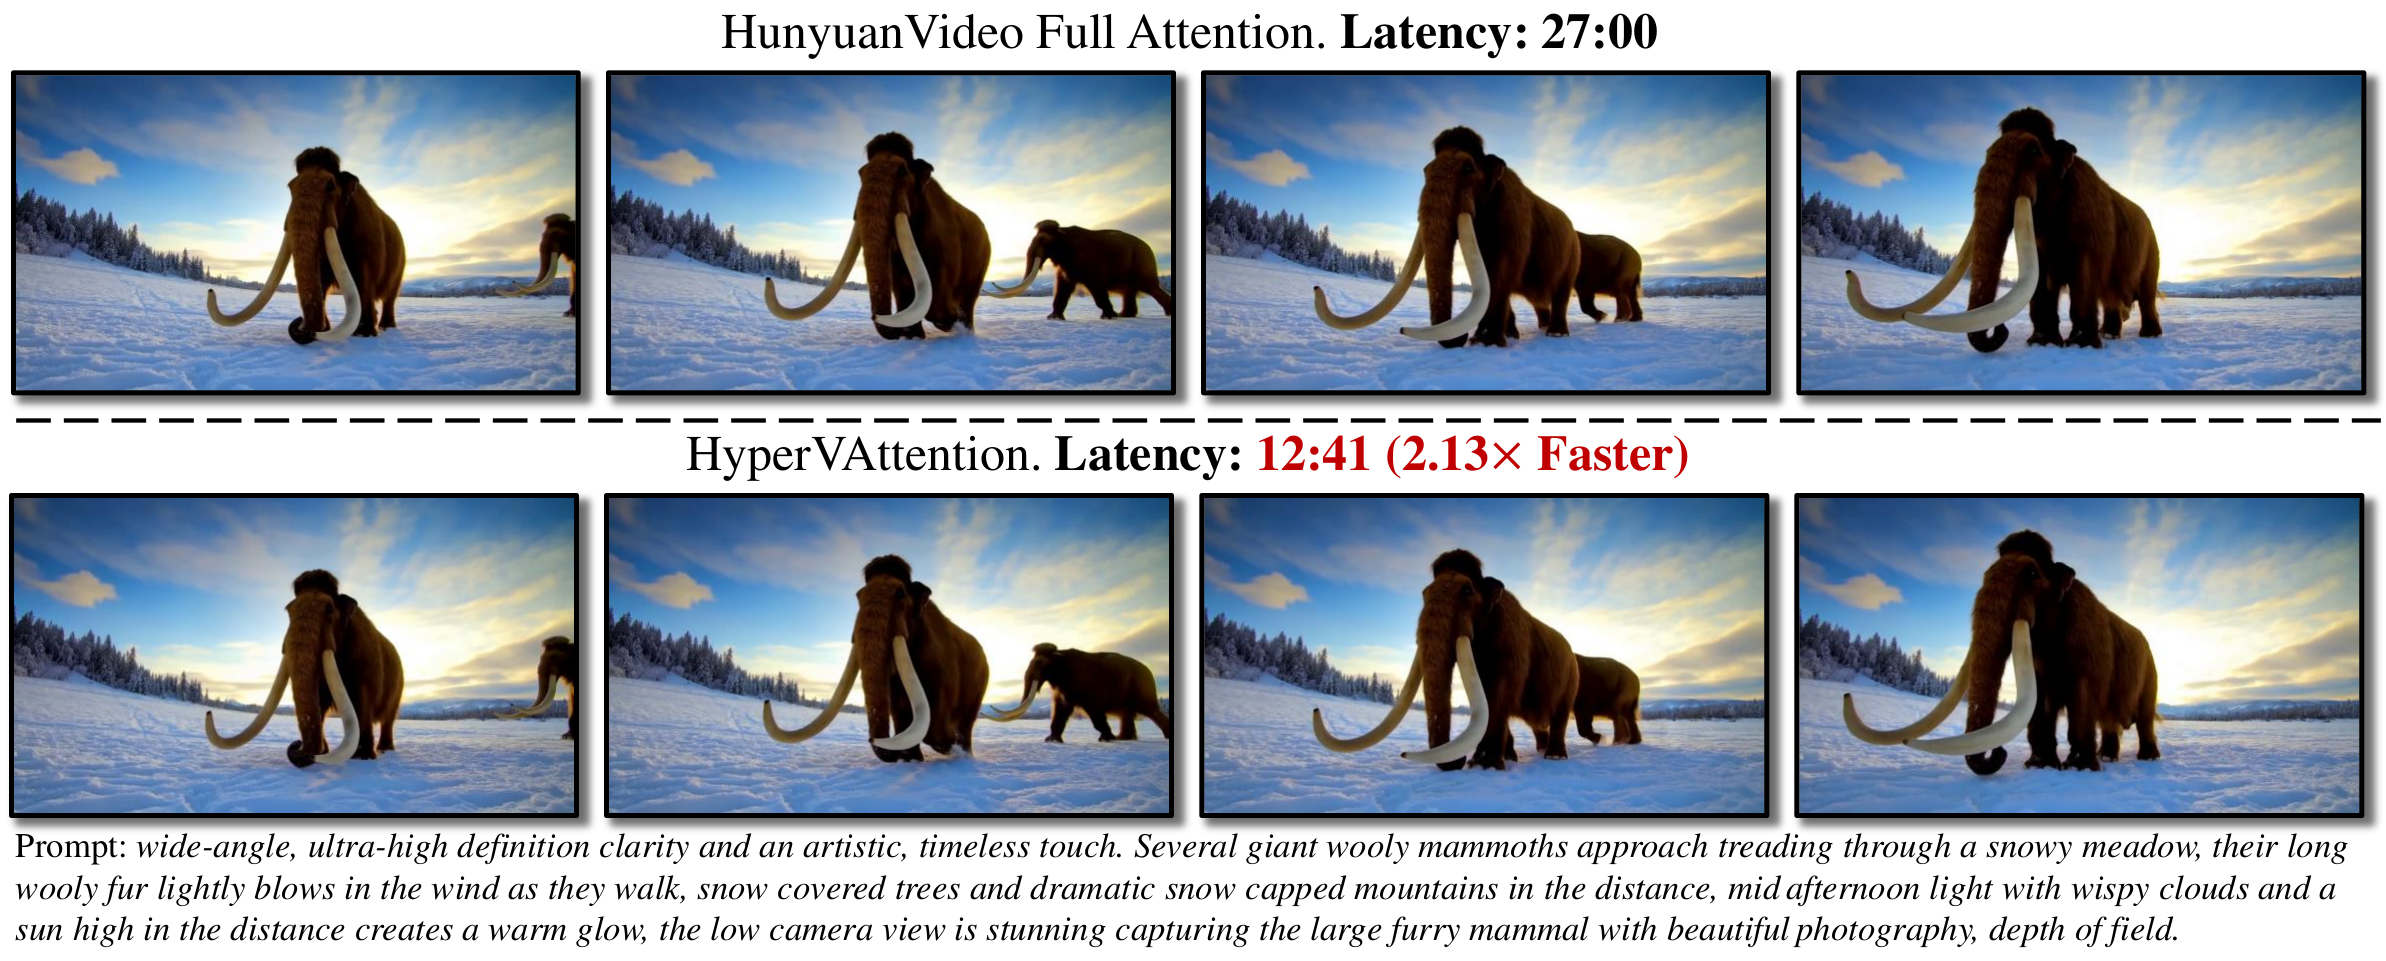
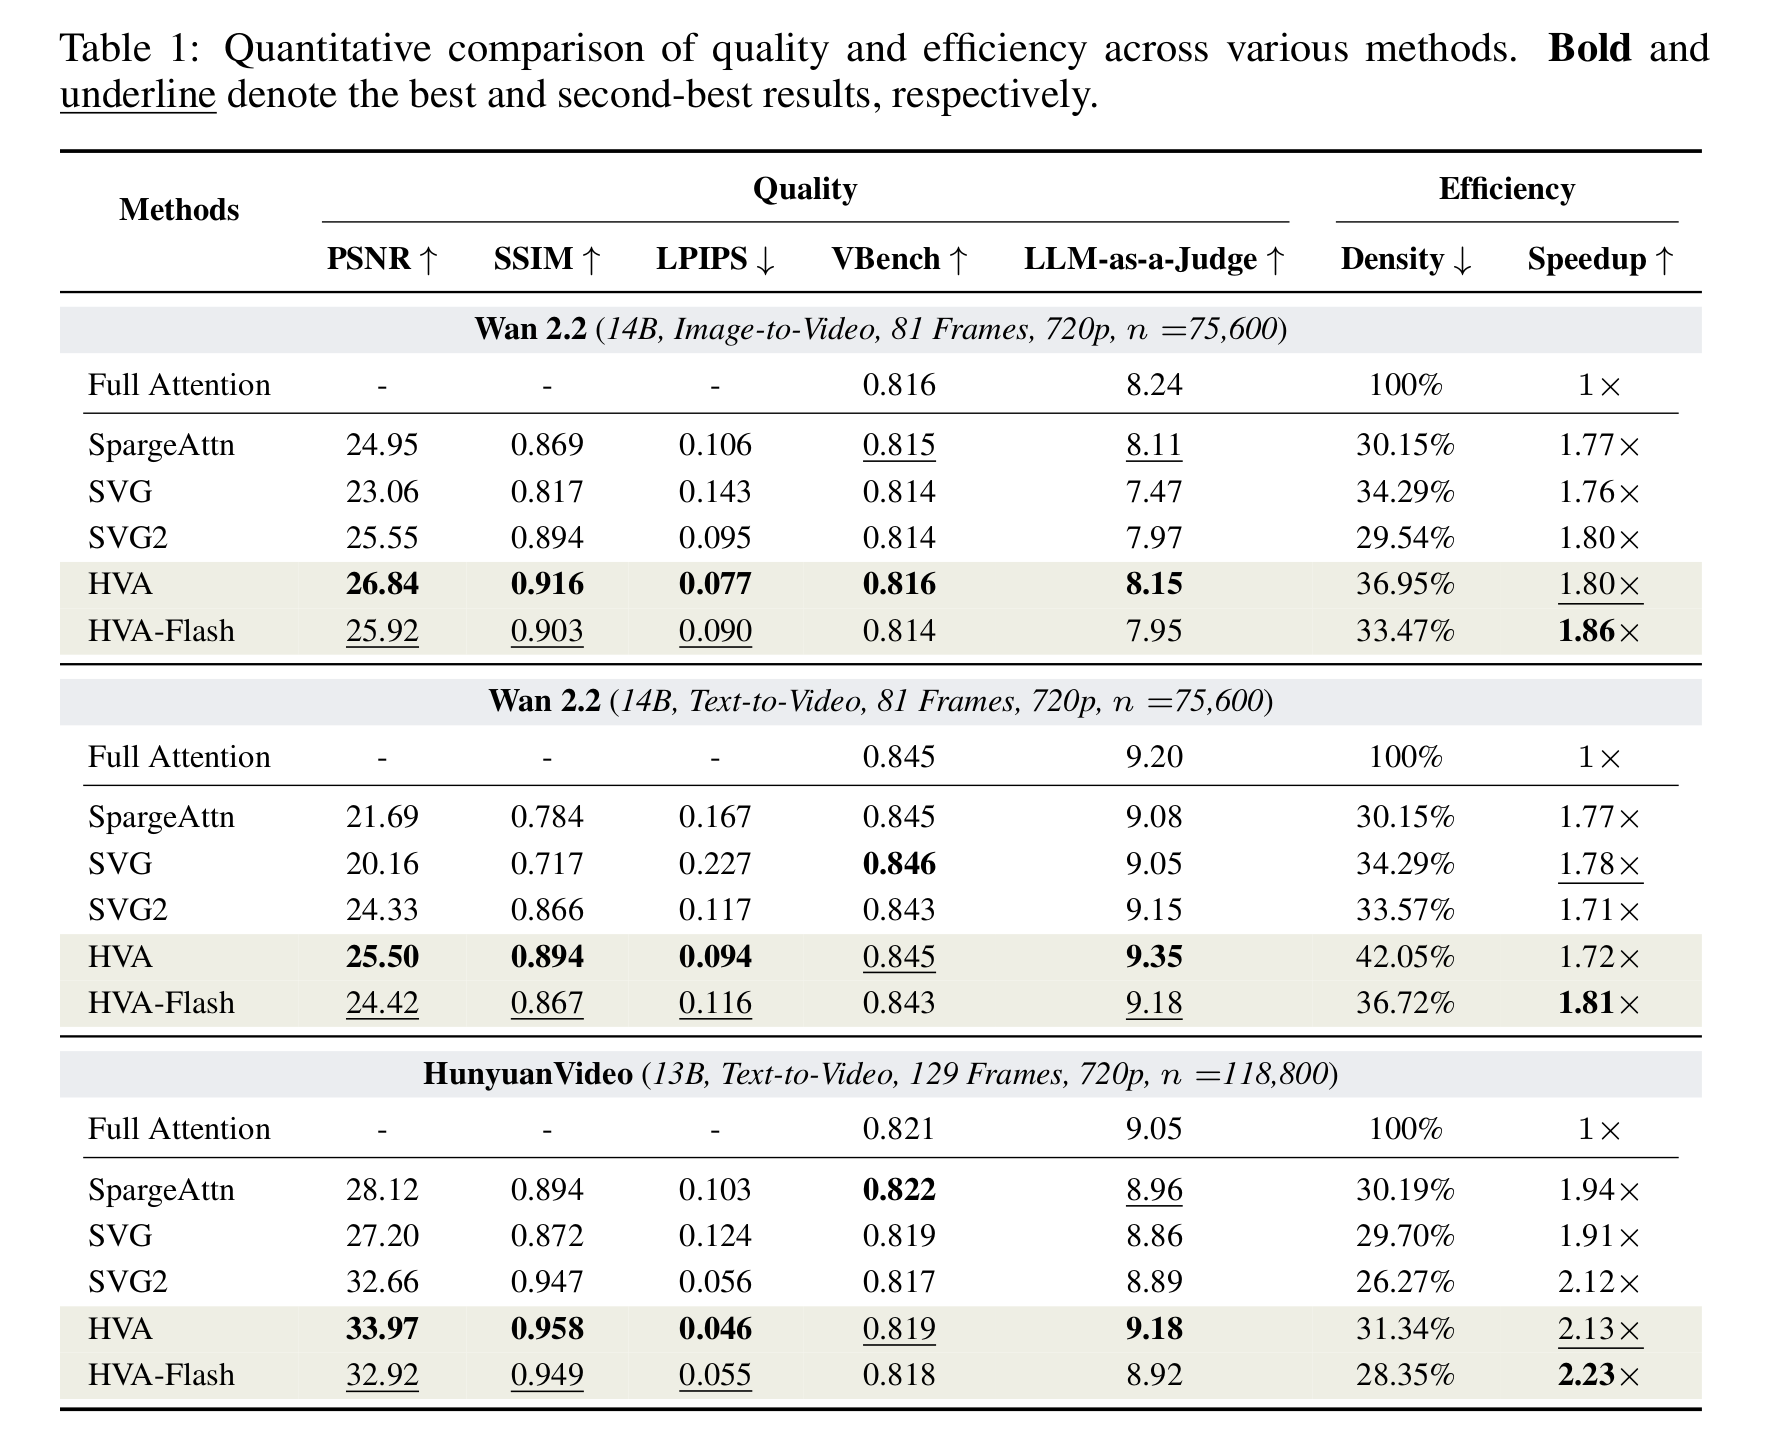
HVA establishes a new Pareto frontier for training-free sparse attention in video diffusion, reducing end-to-end latency
by up to 2.13× while improving fidelity over existing training-free sparse attention baselines.